MABA Studios · Sustainable Edge AI

Intelligence, without the cloud.

Frontier AI, engineered to live on the hardware you already own. No servers. No subscriptions. Nothing leaves your device.

Affan AI Engine 327B · 3.31 GB local
Scroll to explore
Private by design100% on-device

We compress frontier intelligence until it fits in your pocket — private, sustainable, and free of the cloud.

0BParameters in Engine 3
0GBFull model footprint
0MBEngine 3 Mini, 1.7B
0%On-device privacy

Compression
as an art form.

Three generations of quantization-native models, architected at the bit level to keep their reasoning while shedding almost everything else.

01Flagship

Affan AI
Engine 3

A 27B reasoning model built from the ground up to be quantized — flagship analytical depth inside a consumer footprint.

Parameters27B
Footprint3.31GB

Memory footprint · 100% relative

Download
02Compact

Affan AI
Engine 3 Mini

The same engine lineage at 1.7B — full local reasoning that disappears into the memory of a phone.

Parameters1.7B
Footprint204MB

Memory footprint · 6.2% relative

Download
03Ternary

Affan AI
Engine 2 Mini

A 0.6B model in a 1.58-bit ternary weight state. Conversational intelligence at the RAM cost of a 720p video.

Parameters0.6B
Footprint240MB

Memory footprint · 7.3% relative

GitHub
Interactive · Compression lab

Drag to compress.

One engine line, three footprints. Move the slider or tap a stage to watch 27B become phone-sized.

Tap to cycle
01 — Flagship

Affan AI Engine 3

Flagship reasoning, built at 27B and compressed into a 3.31 GB local footprint.

Params27B
Footprint3.31 GB
ClassDesktop
100% of flagship footprint

All engines execute 100% locally · zero cloud calls · zero telemetry

Built for the device
in your pocket.

A studio that ships. From an offline Android assistant on Google Play to the infrastructure that follows your files across every cloud.

Live on Google Play Android

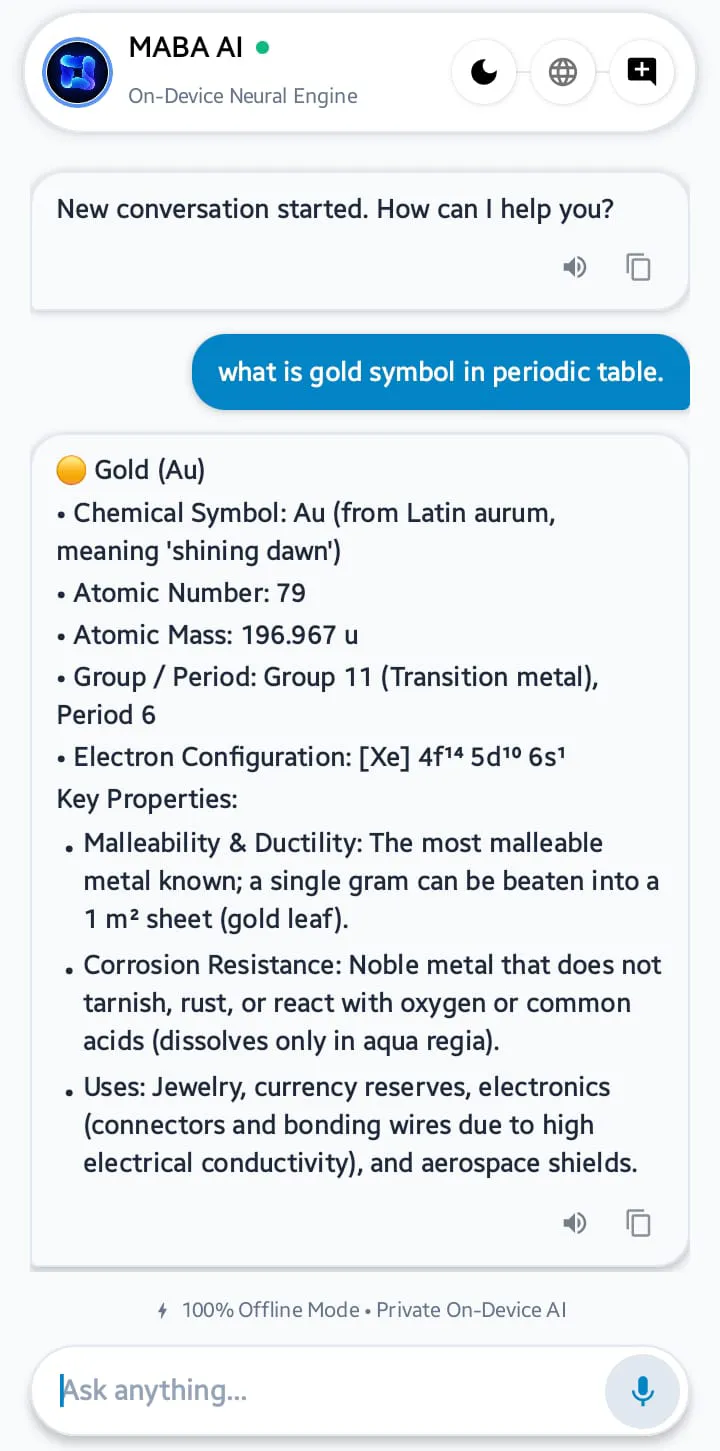
MABA AI

Your own intelligence. Fully offline.

A private Android assistant with real-time token streaming, voice interaction and adjustable RAM governance — running entirely on your phone.

  • 100% on-device inference, zero cloud
  • Zero subscriptions, zero API fees
  • Jetpack Compose · light & OLED modes
GET IT ONGoogle Play Free · No account
Android

MABA Link

Your PC's brain, in your pocket. A private client for LM Studio — chat with your own models over Wi-Fi while chats and keys stay on your device.

Local networkDownload
Windows

Virtual HDD

Every cloud, one drive letter. Unifies Google Drive, TeraBox and a local cache into a single mounted virtual disk with smart read-through caching.

Unified storageDownload

Nothing
leaves this room.

Every prompt is processed by weights sitting in your own memory. No inference server, no telemetry pipeline, no data trail to lose.

  1. 01
    Your prompt

    Typed, spoken or captured on your hardware.

  2. 02
    The model

    Weights resident in local memory, compressed to a fraction of their original size.

  3. 03
    The answer

    Generated token by token, offline, in milliseconds.

Inference runs where the data lives.

maba://local-session Air-gapped
SYSTEM runtime loaded · network interfaces: none
MABA

Ask me anything. This session runs on this device — there is nowhere for your words to go.

NETWORK 0 B WEIGHTS LOCAL IDLE

Interactive local demo · no request leaves this page

The future
runs locally.

Building edge AI, shipping on Android, or exploring on-device inference?
Let's make something that runs on its own.